On Monday, NYU’s Tristan Buckmaster released a statement detailing an absurd and somewhat suspicious encounter he recently had with OpenAI.
Over the past year, the NYU professor worked with a colleague, Anthropic’s in-house mathematician Levent Alpöge, on a set of elusive fluid dynamics problems, using LLMs like OpenAI’s Codex, where they had put draft projects. Their research centered on soft forcing, a niche direction that Buckmaster says almost no one else was pursuing.
After a major breakthrough in August, Buckmaster learned that rumors about their work had reached OpenAI and contacted the company on September 3.
This started a series of conversations better read directly from Buckmasterbut which went something like this:
- OpenAI told Buckmaster that an internal model produced a forced Navier-Stokes result (involving the famously difficult equations describing the motion of viscous fluids) using fluid forcing, the same niche direction that he and Levent were pursuing. OpenAI later admitted that its efforts began a few days earlier, after hearing the same rumor.
- Buckmaster asked if the model had seen or been trained at the Codex sessions containing their drafts. He was told he wasn’t “looking for user data,” but said he never received an answer to the training question.
- OpenAI researcher Sebastien Bubeck proposed coordinating their releases, including an option that Buckmaster would present OpenAI’s results alone. Buckmaster says Bubeck wanted Levent removed because he worked at Anthropic, while offering to say the couple deserved the $1 million Clay Prize.
- When Buckmaster refused and said he would make it public, he was asked, “Why would you want to ruin your career?”
OpenAI denies accessing their unpublished work or using their prompts to direct its agents, although it also states that it “cannot rule out” that anonymized data from their use of its products helped improve its models.
We congratulate Levent Alpöge and Tristan Buckmaster for their remarkable mathematical work.
We (the researchers and agents) did not see any of their work through any means until they made it public – in particular, no specific user data was accessed in order to resolve… https://t.co/otJKRHnQgb
-OpenAI (@OpenAI) September 8, 2026
Buckmaster emphasizes that he does not know whether his data was used and is not accusing OpenAI of theft. Still, the strange overlap, the proposed credit deal, and the lingering question of training make me raise one eyebrow, if not both.
Regardless of what actually happened, what strikes me is the growing distrust of these models as their capabilities increase. Personally, I find myself increasingly willing to share more with AI while becoming increasingly wary of what I share. It’s not as if people don’t know their data can be used, but this matter seems more difficult as the models improve significantly and the information we provide them becomes more valuable. Personal agents only take this further, demanding access to our files, our work, our preferences, our conversations, and everything else we let them touch to be truly useful.
Do you like this article?
Subscribe to Bankless or log in
Palantir CEO Alex Karp recently described a similar concern among enterprise customers, wondering: “Why would they have access to my data if they want to create my alpha?”
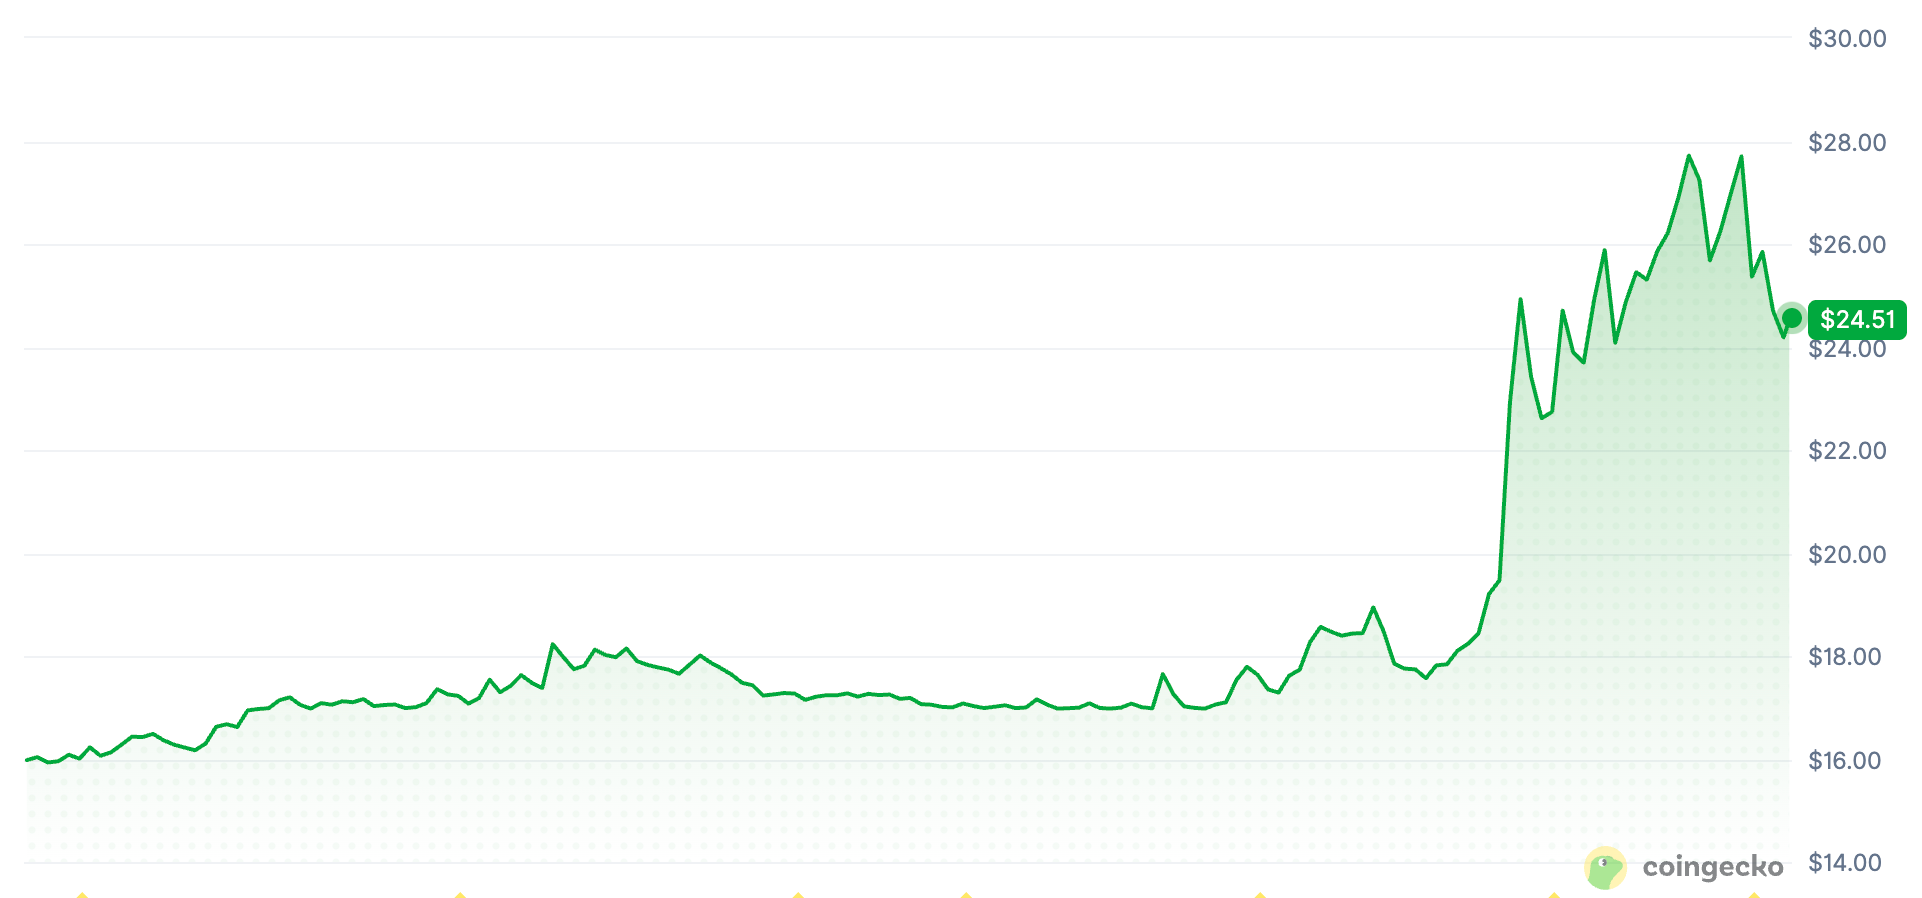
Amid this debacle, $VVV, the governance token of Venice, skyrocketed yesterday, increasing by around 40% to new all-time highs. The fit is obvious: a private inference platform capturing supply as distrust mounts over frontier lab data policies.
Venice may be the headliner here, but it’s just one of many inference marketplaces offering open and flexible access to intelligence, allowing users to leverage different models for different tasks rather than committing to a single vendor. In crypto, these markets saw particularly rapid growth around x402, where inference became one of the clearest early use cases for the protocol.
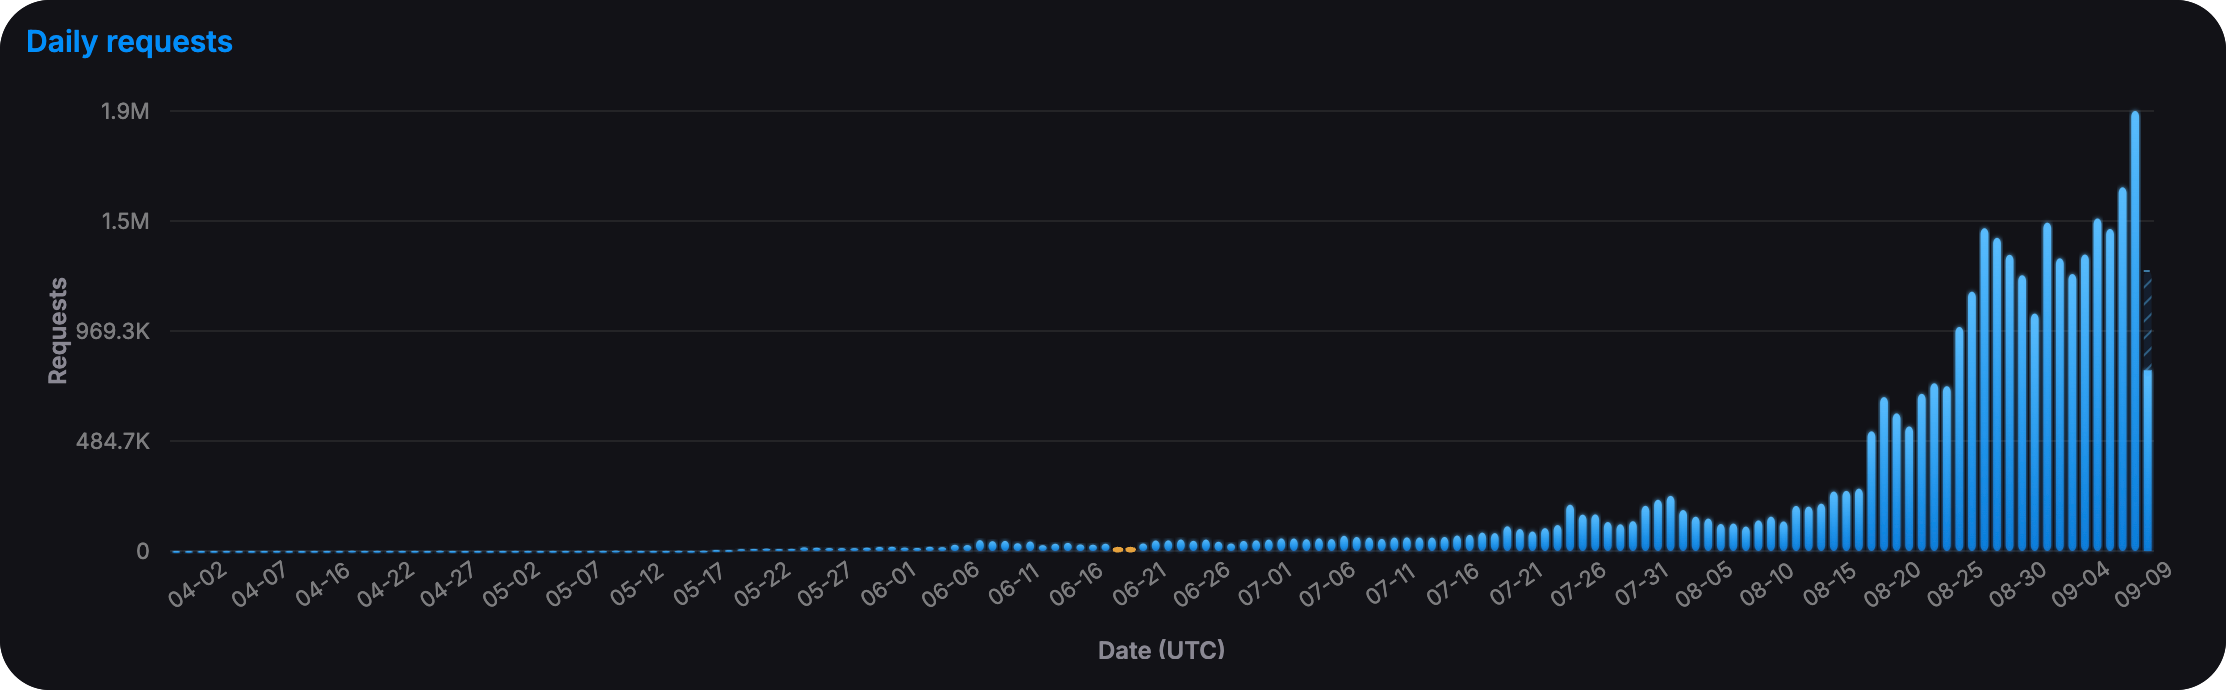
BlockRun, an inference gateway, is currently Largest active merchant in x402 in number of transactions, while Surplus Intelligence experienced its biggest day on record for requests yesterday. There is clearly a growing demand for accessing intelligence through these open markets.
These avenues also provide an increasingly relevant privacy by-product: pseudonymity. Paying from a wallet rather than through an account directly linked to an email address, card, or KYC profile creates some separation between the person making the request and the lab that ultimately processes it.
Of course, the final model provider always sees the actual prompt, and very specific work can identify its author even without a name. But a router can decouple part of the direct link between user and lab, while platforms like Venice can go further with retention-free, TEE, or end-to-end encrypted models.
The catch is that the strictest verifiable privacy today generally requires moving away from hard-frontier models controlled by OpenAI, Anthropic, or Google. There remains a trade-off between border intelligence and the degree of control users can maintain over their data.
However, as the information we feed to AI becomes more valuable, I expect this separation to matter more. Open inference markets, especially on-chain ones, appear to be a first step toward more controlled access to intelligence: giving users more choice, abstracting away part of their identity, and creating a foundation on which stronger privacy can be built.